publications

Research outputs by year, newest first.

This page is organized like an academic portfolio rather than a raw paper list. Full BibTeX is available here.

2026

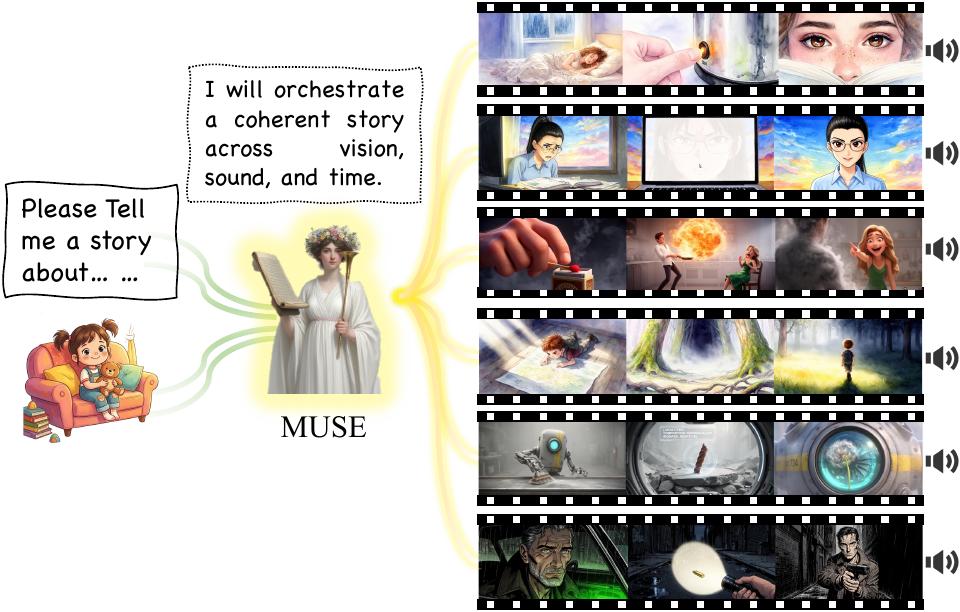
MUSE: A Multi-agent Framework for Unconstrained Story Envisioning via Closed-Loop Cognitive Orchestration

W. Sun, Z. Wang, Z. Hu, C. Wang, H. Li, W. Chen.
ACM Multimedia Workshop on Agentic Multimodal Intelligence 2026
paperproject
MUSE long-form audio-visual storytelling teaser

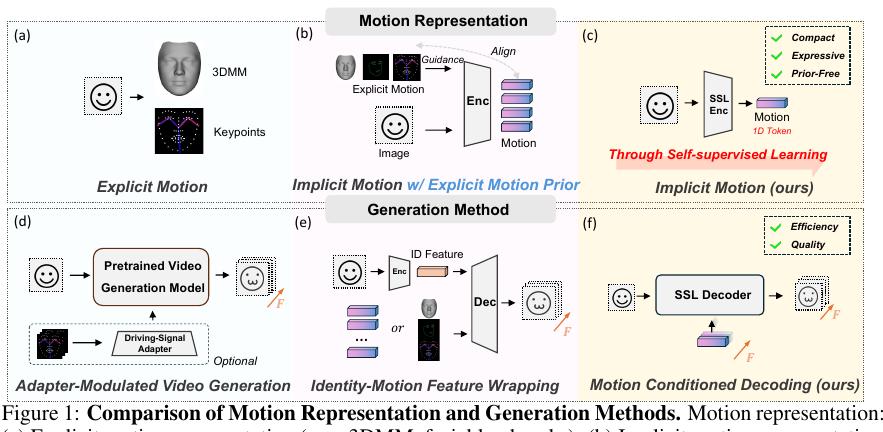
SeMo: A Self-supervised Motion Latent for Portrait Video Generation

Q. Zhang, C. Wu, W. Sun, H. Liu, et al.
ACM MM 2026 Oral
paper
SeMo motion representation and generation overview

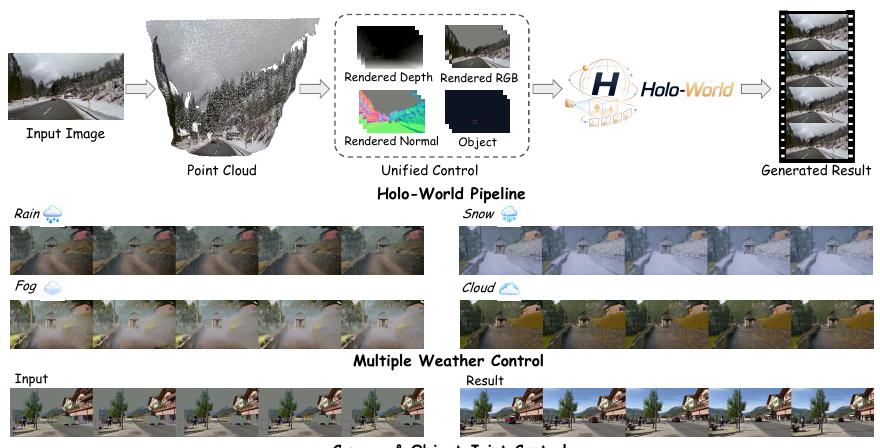
Holo-World: Unified Camera, Object and Weather Control for Video World Model

Xiangchen Yin, Wenzhang Sun, Jiahui Yuan, Zijie Liu, Yinda Chen, Wei Li, Dachun Kai, Chunfeng Wang, Xiaoyan Sun.
arXiv 2026
paperproject
Holo-World unified camera, object, and weather control teaser

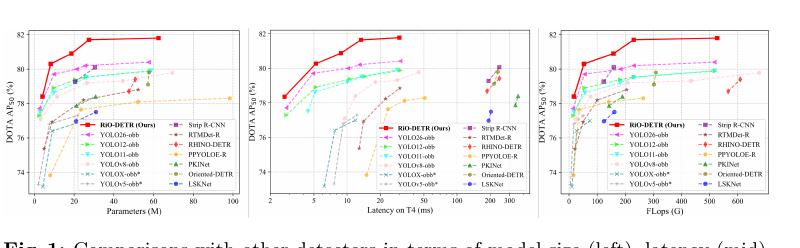
RiO-DETR: DETR for Real-time Oriented Object Detection

Z. Hu, Y. Zhao, Y. Peng, W. Sun, et al.
ECCV 2026 Oral
paper
RiO-DETR speed and accuracy comparison

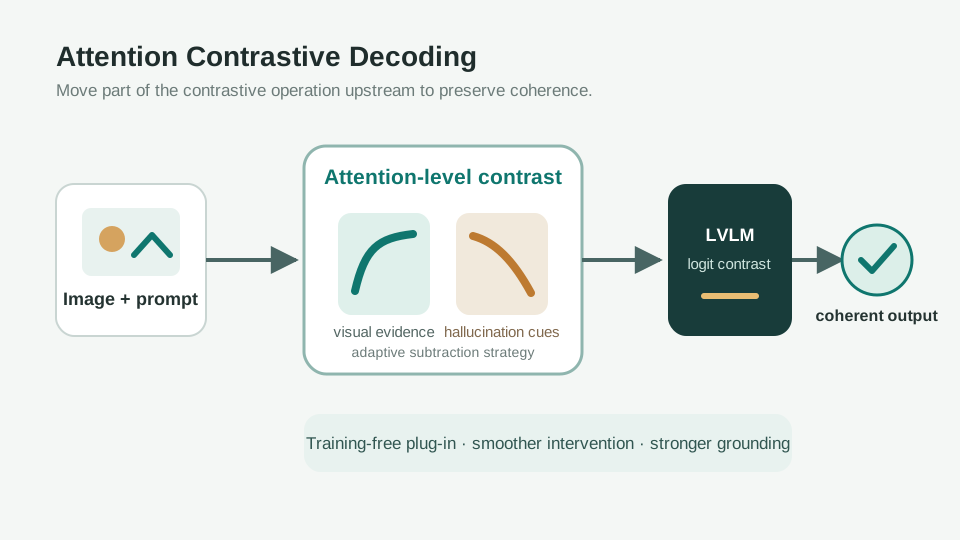
Beyond Logits: Coherent Hallucination Mitigation via Attention Contrastive Decoding

Yujia Chen, Rui Sun, Wangkai Li, Huayu Mai, Bingzhou Wang, Zhangyu He, Aibing Li, Wenzhang Sun, Tianzhu Zhang.
ICML 2026
paper
Attention Contrastive Decoding overview

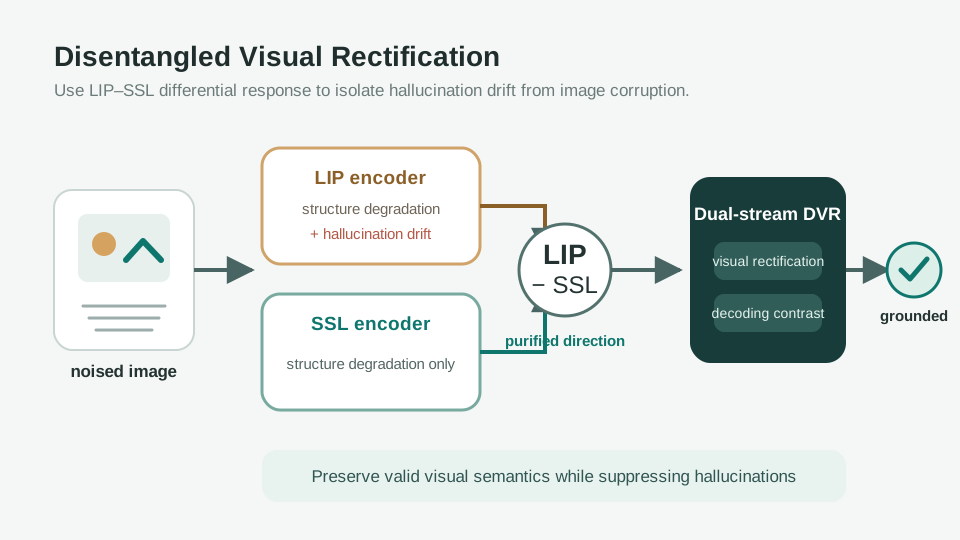
Beyond Blind Noising: Disentangled Visual Rectification for Hallucination Mitigation in MLLMs

Yujia Chen, Rui Sun, Zhaoyang Li, Wangkai Li, Huayu Mai, Bingzhou Wang, Aibing Li, Wenzhang Sun.
ICML 2026
paper
Disentangled Visual Rectification overview

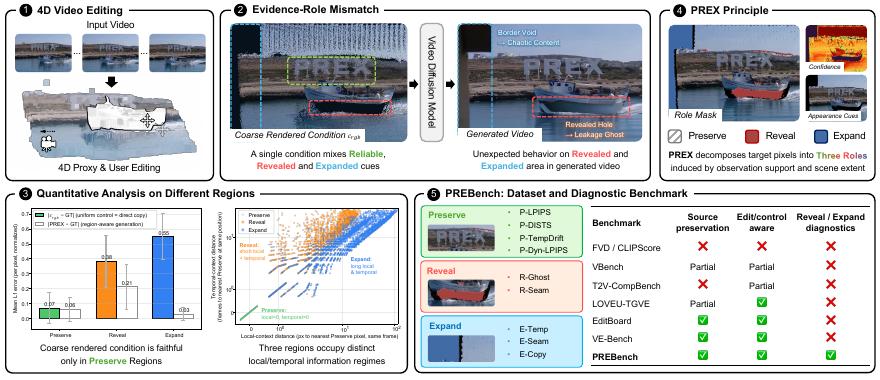
Preserve, Reveal, Expand: Faithful 4D Video Editing with Region-Aware Conditioning

Zhangchi Hu, Wenzhang Sun, Xiangchen Yin, Jiahui Yuan, Chunfeng Wang, Hao Li, Kun Zhan, Xiaoyan Sun. Project Leader.
arXiv 2026
paperproject
PREX and PREBench overview

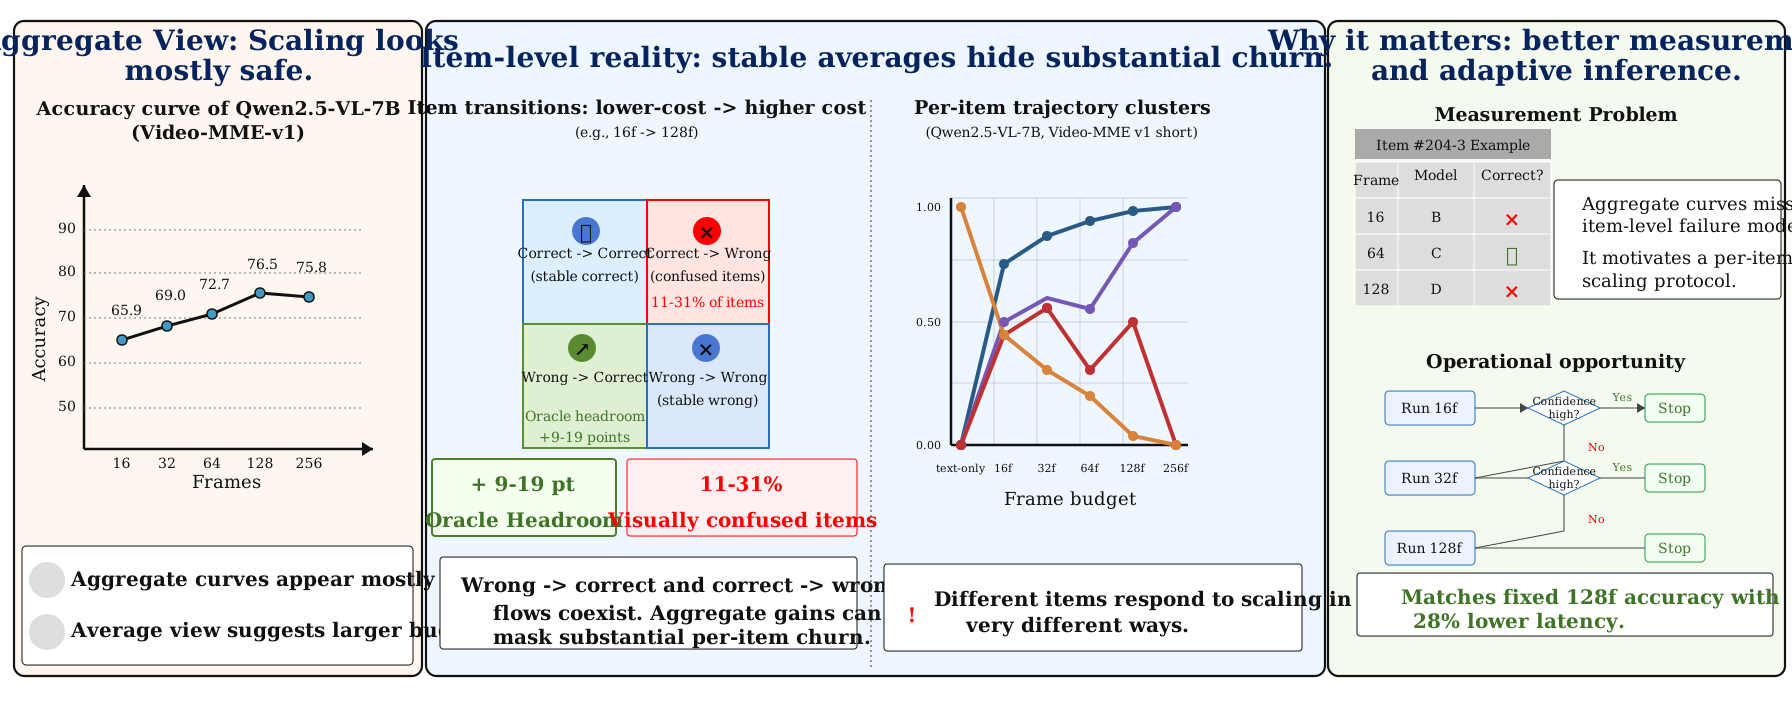
Stable Curves, Unstable Items: Item-Level Scaling Heterogeneity in Video LLMs

Wenzhang Sun, Chunfeng Wang, Xiangchen Yin, Yujia Chen, Hao Li, Kun Zhan.
arXiv 2026
code
Video LLM item-level scaling overview

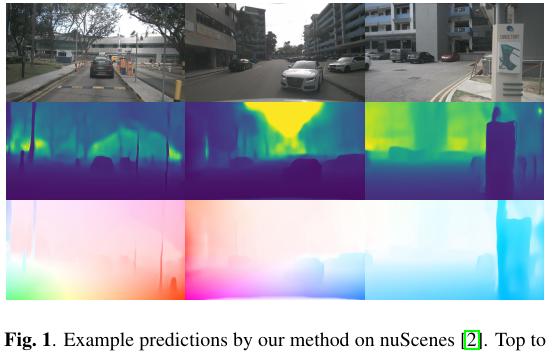
DrivingScene: A Multi-Task Online Feed-Forward 3D Gaussian Splatting Method for Dynamic Driving Scenes

Q. Hou, W. Sun, C. Zeng, C. Wang, H. Li, J. Cui.
ICASSP 2026
paper
DrivingScene depth and optical-flow predictions

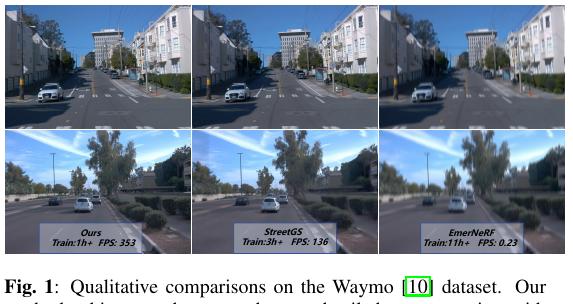
PAGS: Priority-Adaptive Gaussian Splatting for Dynamic Driving Scenes

A. Ying, W. Sun, C. Zeng, C. Wang, H. Li, J. Cui.
ICASSP 2026
paper
PAGS dynamic driving-scene reconstruction comparison

2025

UniCP: A Unified Caching and Pruning Framework for Efficient Video Generation

W. Sun, Q. Hou, D. Di, J. Yang, Y. Ma, J. Cui.
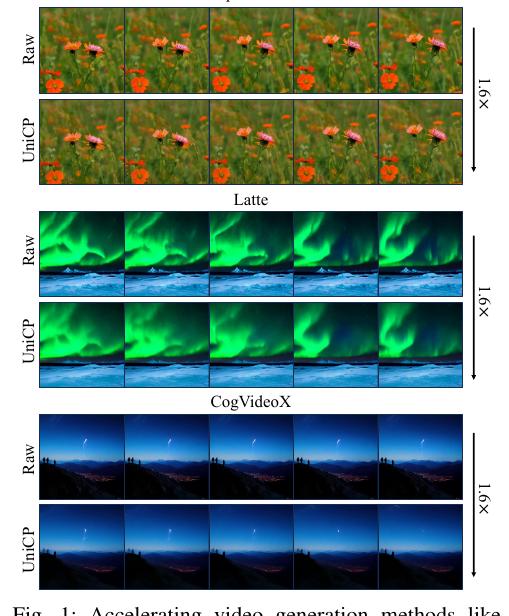
MMAsia 2025
paper
UniCP video generation comparison

DeCo-VAE: Learning Compact Latents for Video Reconstruction via Decoupled Representation

X. Yin, J. Yuan, Z. Hu, W. Sun, et al.
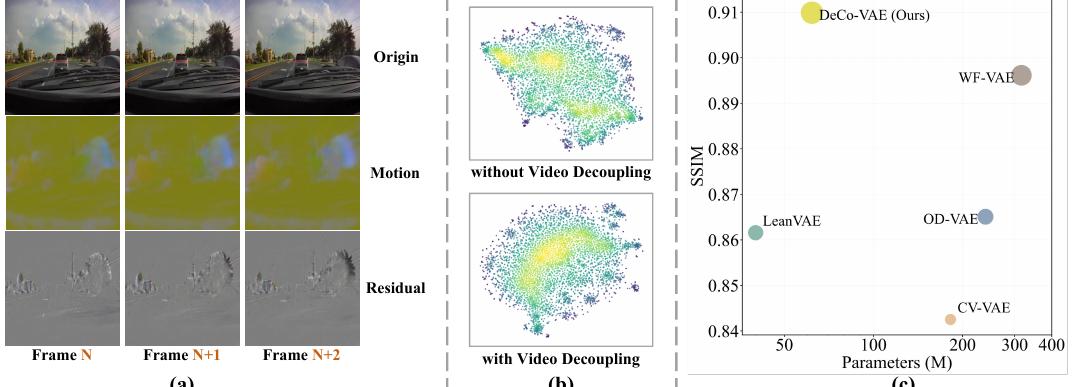
arXiv 2025
paper
DeCo-VAE decoupled video representation overview

TV-3DG: Mastering Text-to-3D Customized Generation with Visual Prompt

Jiahui Yang, Donglin Di, Baorui Ma, Jianxun Cui, Xun Yang, Yongjia Ma, Wenzhang Sun, Wei Chen, Zhou Xue, Meng Wang, Yebin Liu.
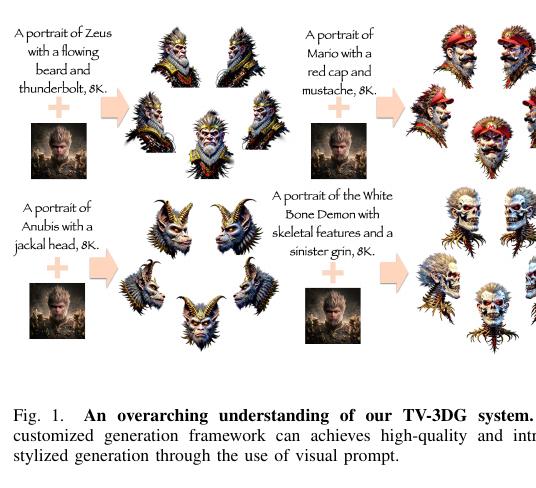
TPAMI 2025
paper
TV-3DG customized 3D generation examples

FaceVid-1K: A Large-Scale High-Quality Multiracial Human Face Video Dataset

D. Di, H. Feng, W. Sun, Y. Ma, et al.
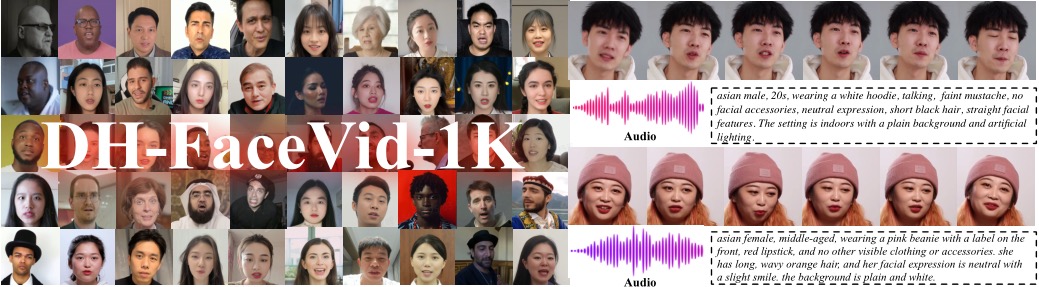
ICCV 2025
project
FaceVid-1K dataset overview

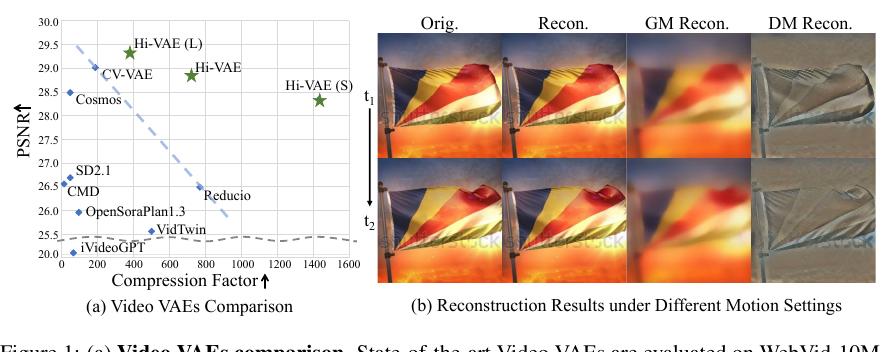
Hi-VAE: Efficient Video Autoencoding with Global and Detailed Motion

H. Liu*, W. Sun*, Q. Zhang, D. Di, et al.
arXiv 2025
paper
Hi-VAE compact video latent comparison

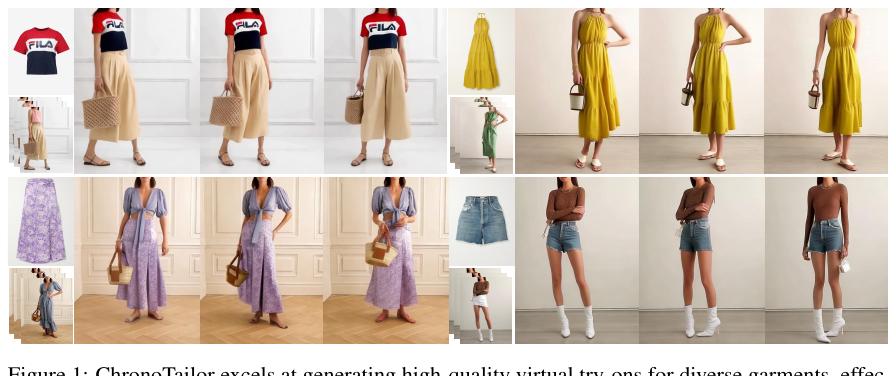
ChronoTailor: Harnessing Attention Guidance for Fine-Grained Video Virtual Try-On

J. Wang*, W. Sun*, M. Li, Y. Zheng, et al.
arXiv 2025
paper
ChronoTailor video virtual try-on results

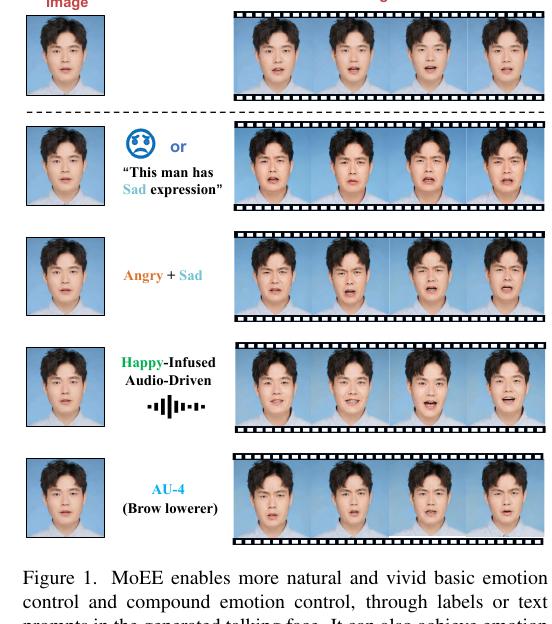
MoEE: Mixture of Emotion Experts for Audio-Driven Portrait Animation

H. Liu, W. Sun, D. Di, S. Sun, J. Yang, C. Zou, H. Bao.
CVPR 2025
paper
MoEE basic and compound emotion control examples

2024 and earlier

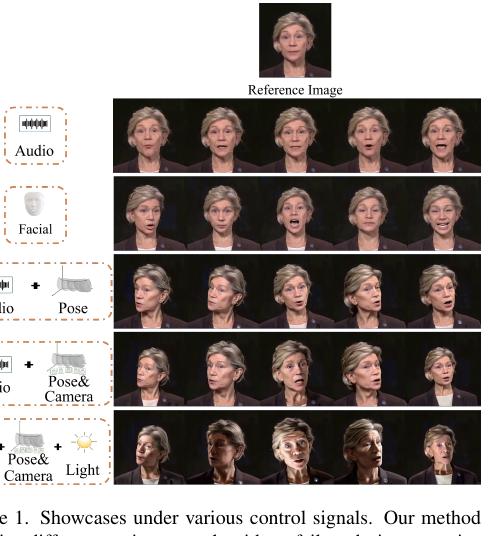
UniAvatar: Taming Lifelike Audio-Driven Talking Head Generation with Comprehensive Motion and Lighting Control

W. Sun, X. Li, D. Di, Z. Liang, Q. Zhang, H. Li, W. Chen, J. Cui.
arXiv 2024
paper
UniAvatar motion and lighting control examples

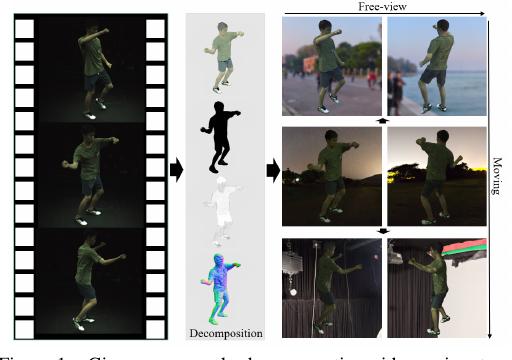
Neural Reconstruction of Relightable Human Model from Monocular Video

W. Sun, Y. Che, H. Huang, Y. Guo.

ICCV 2023
paper
Relightable human reconstruction teaser

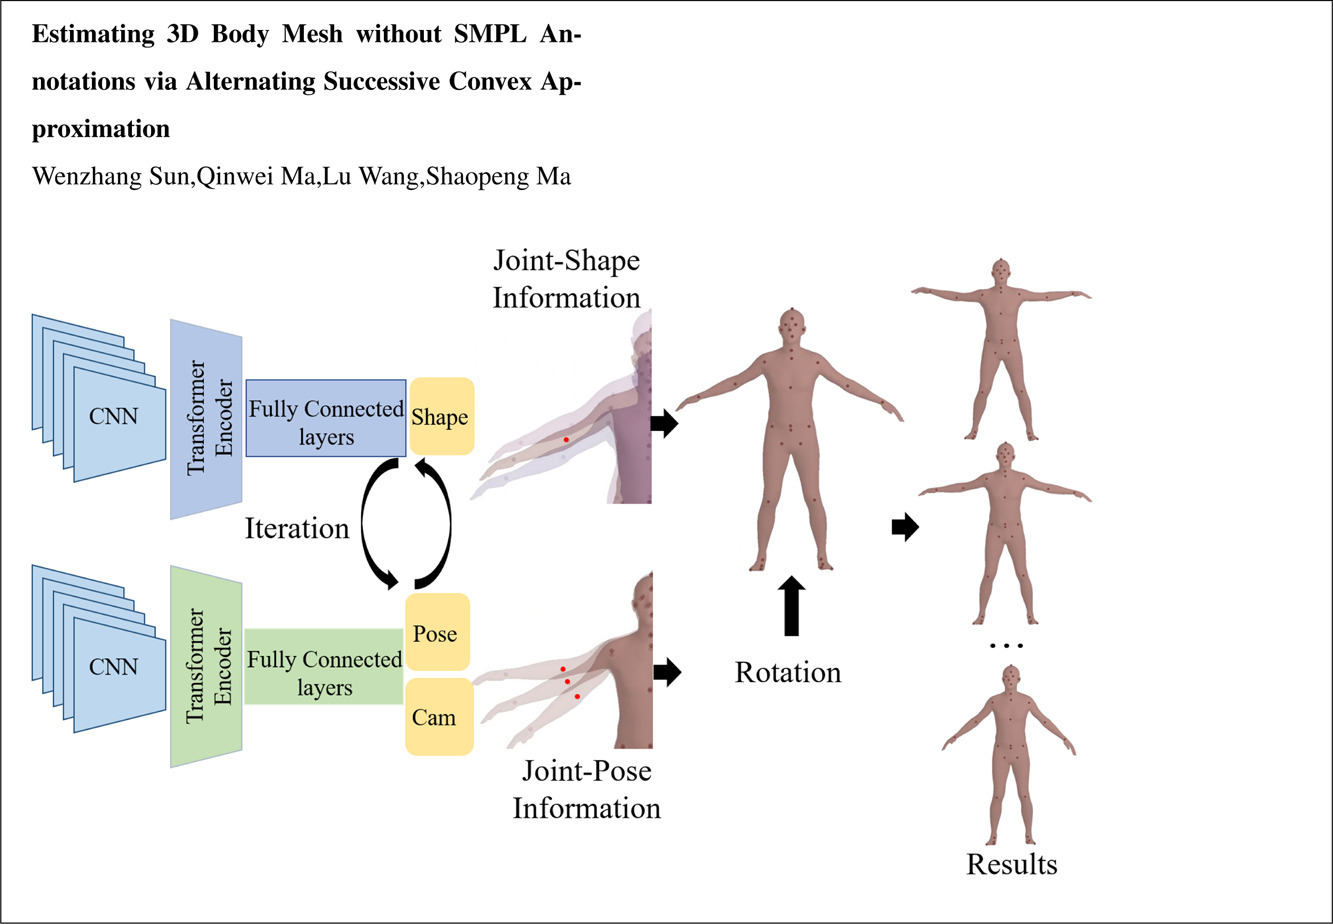
Estimating 3D Body Mesh without SMPL Annotations via Alternating Successive Convex Approximation

W. Sun, L. Wang, S. Ma, Q. Ma.

CVIU 2022
Alternating shape and pose estimation architecture